Image: xiaomi-robotics-0.github.io
Xiaomi's open-sourced VLA model optimized for smooth real-time execution on consumer GPUs.
Key specs
| Params | 4.7B |
|---|
| Architecture | Qwen3-VL-4B-Instruct VLM + DiT (flow matching) |
|---|
| License | Apache 2.0 |
|---|
Technical details
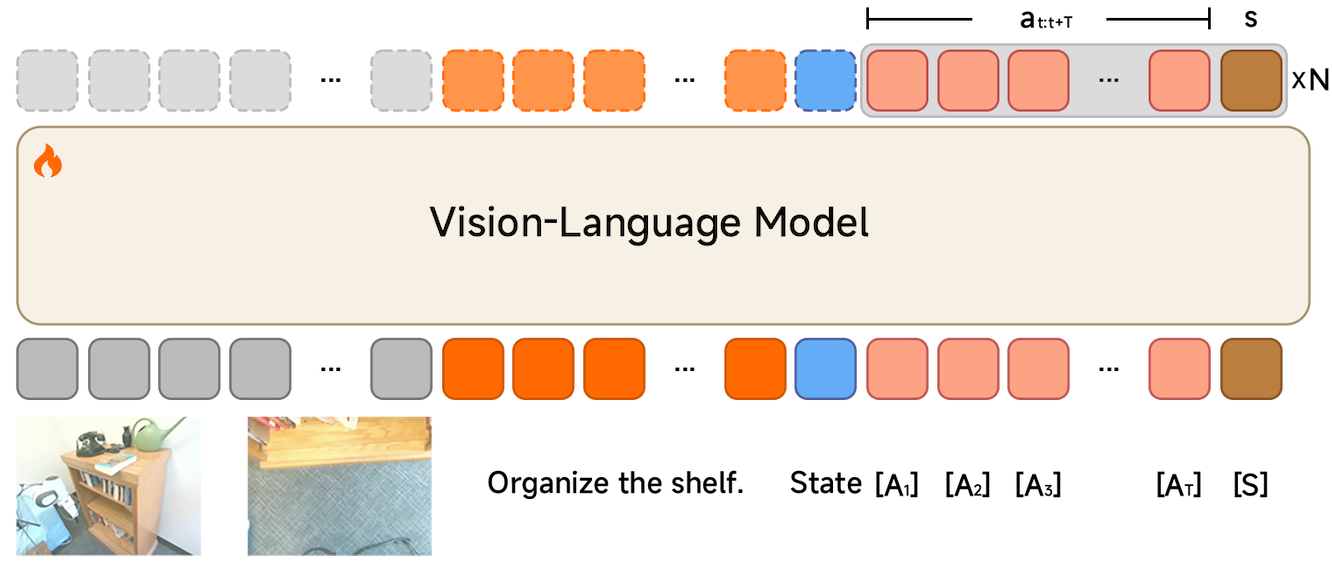
Xiaomi-Robotics-0 is Xiaomi's open-source 4.7B-parameter VLA optimized for high performance and smooth real-time execution. It is pre-trained on cross-embodiment robot trajectories plus vision-language data to avoid forgetting the VLM's visual-semantic knowledge, then post-trained for asynchronous execution, with consecutive action chunks timestep-aligned at deployment. Xiaomi reports 98.7% on LIBERO, 4.80 average length on CALVIN ABCD→D and 79.2% on SimplerEnv WidowX, and real-time rollouts on a consumer GPU. Pre-trained and fine-tuned weights, inference/eval code and post-training code are released under Apache-2.0.
| Architecture | Vision-language-action model built on a pre-trained VLM with an action-generation component, trained for asynchronous execution with timestep-aligned consecutive action chunks for smooth real-time rollouts. |
|---|
| Params | 4.7B |
|---|
| Inputs outputs | Inputs: camera images, language instruction, robot state; outputs: continuous action chunks. |
|---|
| Training data | Pre-trained on large-scale cross-embodiment robot trajectories and vision-language data; fine-tuned checkpoints for LIBERO, CALVIN and SimplerEnv (Fractal, Bridge). |
|---|
| Embodiments supported | Simulation: LIBERO, CALVIN, SimplerEnv Google Robot and WidowX; real-world bimanual manipulation tasks. |
|---|
| License weights | Apache-2.0 |
|---|
| License code | Apache-2.0 |
|---|
| Hardware requirements | Runs real-time on a consumer-grade GPU; compatible with Hugging Face transformers. |
|---|
| Benchmarks claimed | |
|---|
| How to try | github.com/…/Xiaomi-Robotics-0 |
|---|
| Sources | |
|---|
Benchmarks, where listed, are as claimed by the vendor.