 SAIllustration
No official image on file. Showing a schematic category illustration.
Foundation model that learns new long tasks from a single example via in-context learning.
Key specs
| Claims | Learns 10-minute tasks from one video prompt without fine-tuning |
|---|
Technical details
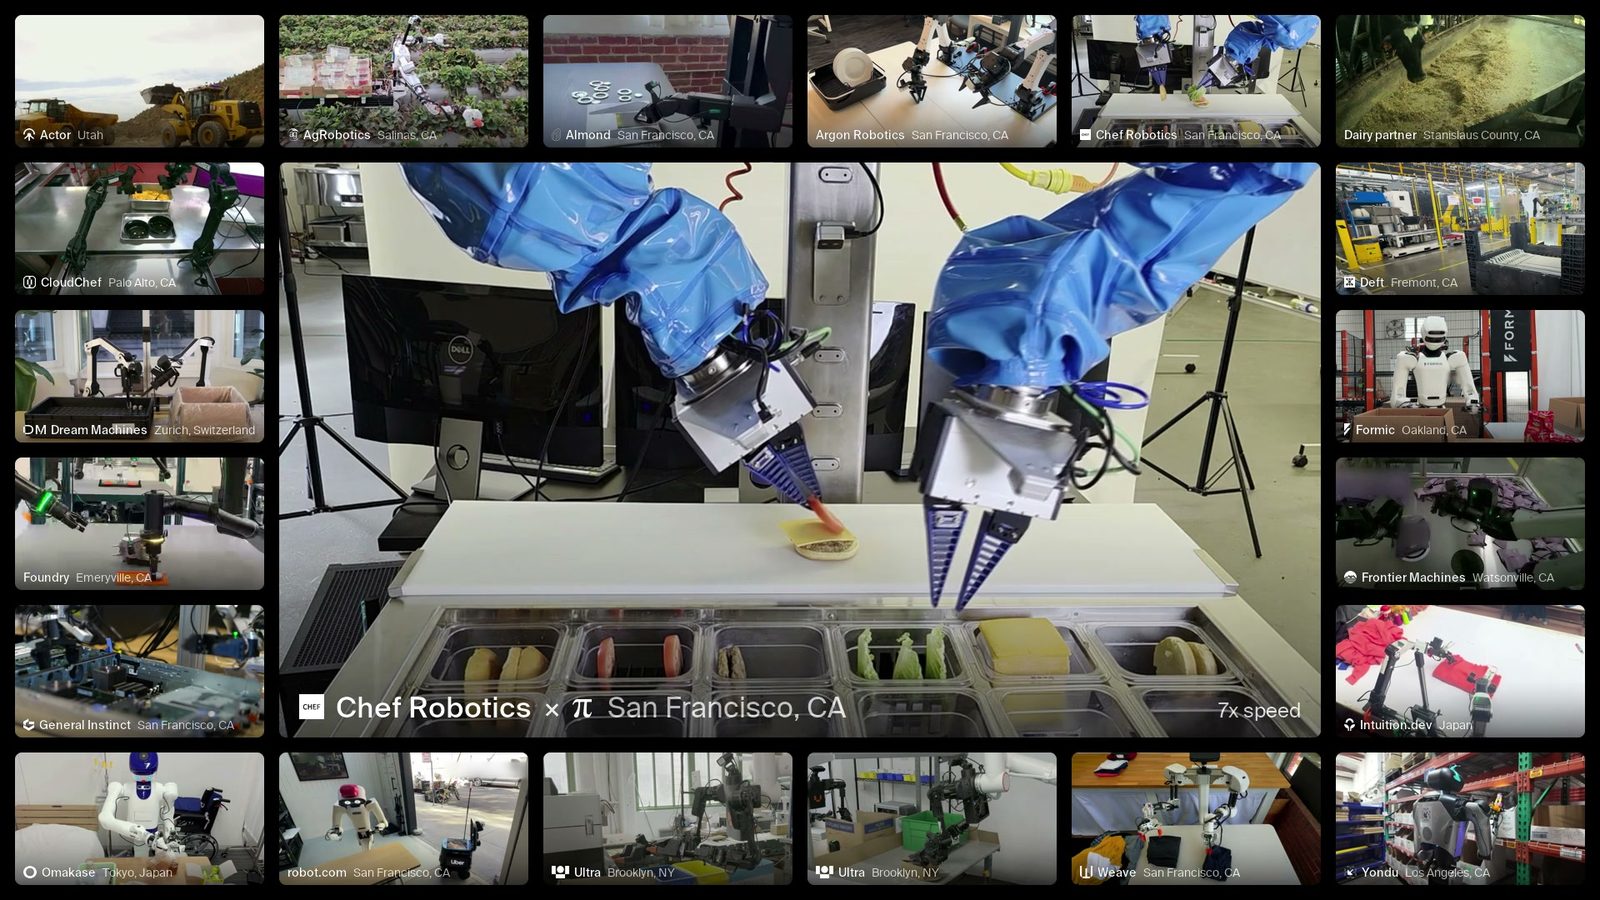
S1 is Skild AI's flagship manipulation foundation model, trained from the ground up for in-context learning: a single video demonstration in the prompt specifies the task, and the same frozen weights execute it, including unseen tasks up to about 10 minutes long (e.g. plant potting, pancake cooking, pour-over coffee, kit assembly). In a controlled study against a language-prompted VLA with identical data, architecture and compute, Skild reports the ICL gap widening with scale, reaching 66% vs 9% cumulative per-step success on unseen long-horizon tasks at 100k hours. Skild also reports robustness to mid-execution perturbations and that one in-context demo roughly matches 380 post-training episodes. The model is not publicly available; it is deployed with commercial partners.
| Architecture | Robot foundation model built as an in-context learner: a video demonstration of the task is placed in the context window and the policy translates it into actions for its own embodiment and scene; no weight updates at test time. |
|---|
| Inputs outputs | Inputs: one video demonstration prompt (can be an egocentric human video from a different scene/viewpoint/embodiment) plus live robot observations; outputs: robot actions. |
|---|
| Training data | Episodic pre-training where the task is specified only through an in-context demonstration; Skild scales robot teleop, UMI, egocentric video and simulation data in-house. Scaling study used 1k-100k hours of pre-training data. |
|---|
| License weights | Proprietary; weights not released. |
|---|
| Hardware requirements | Trained on NVIDIA AI infrastructure; deployment hardware not disclosed. |
|---|
| Benchmarks claimed | | Benchmark | Skild internal long-horizon unseen-task suite (avg cumulative per-step success, 100k h pre-training) |
|---|
| Result | 66% (vs 9% for language-prompted VLA baseline) |
|---|
| Source url | skild.ai/…/s1 |
|---|
| Benchmark | Skild internal seen-task suite (avg cumulative per-step success) |
|---|
| Result | ~96% |
|---|
| Source url | skild.ai/…/s1 |
|---|
| Benchmark | Demonstration efficiency vs VLA post-training on unseen task |
|---|
| Result | 1 in-context demo ≈ 380 post-training episodes |
|---|
| Source url | skild.ai/…/s1 |
|---|
|
|---|
| Sources | |
|---|
Benchmarks, where listed, are as claimed by the vendor.